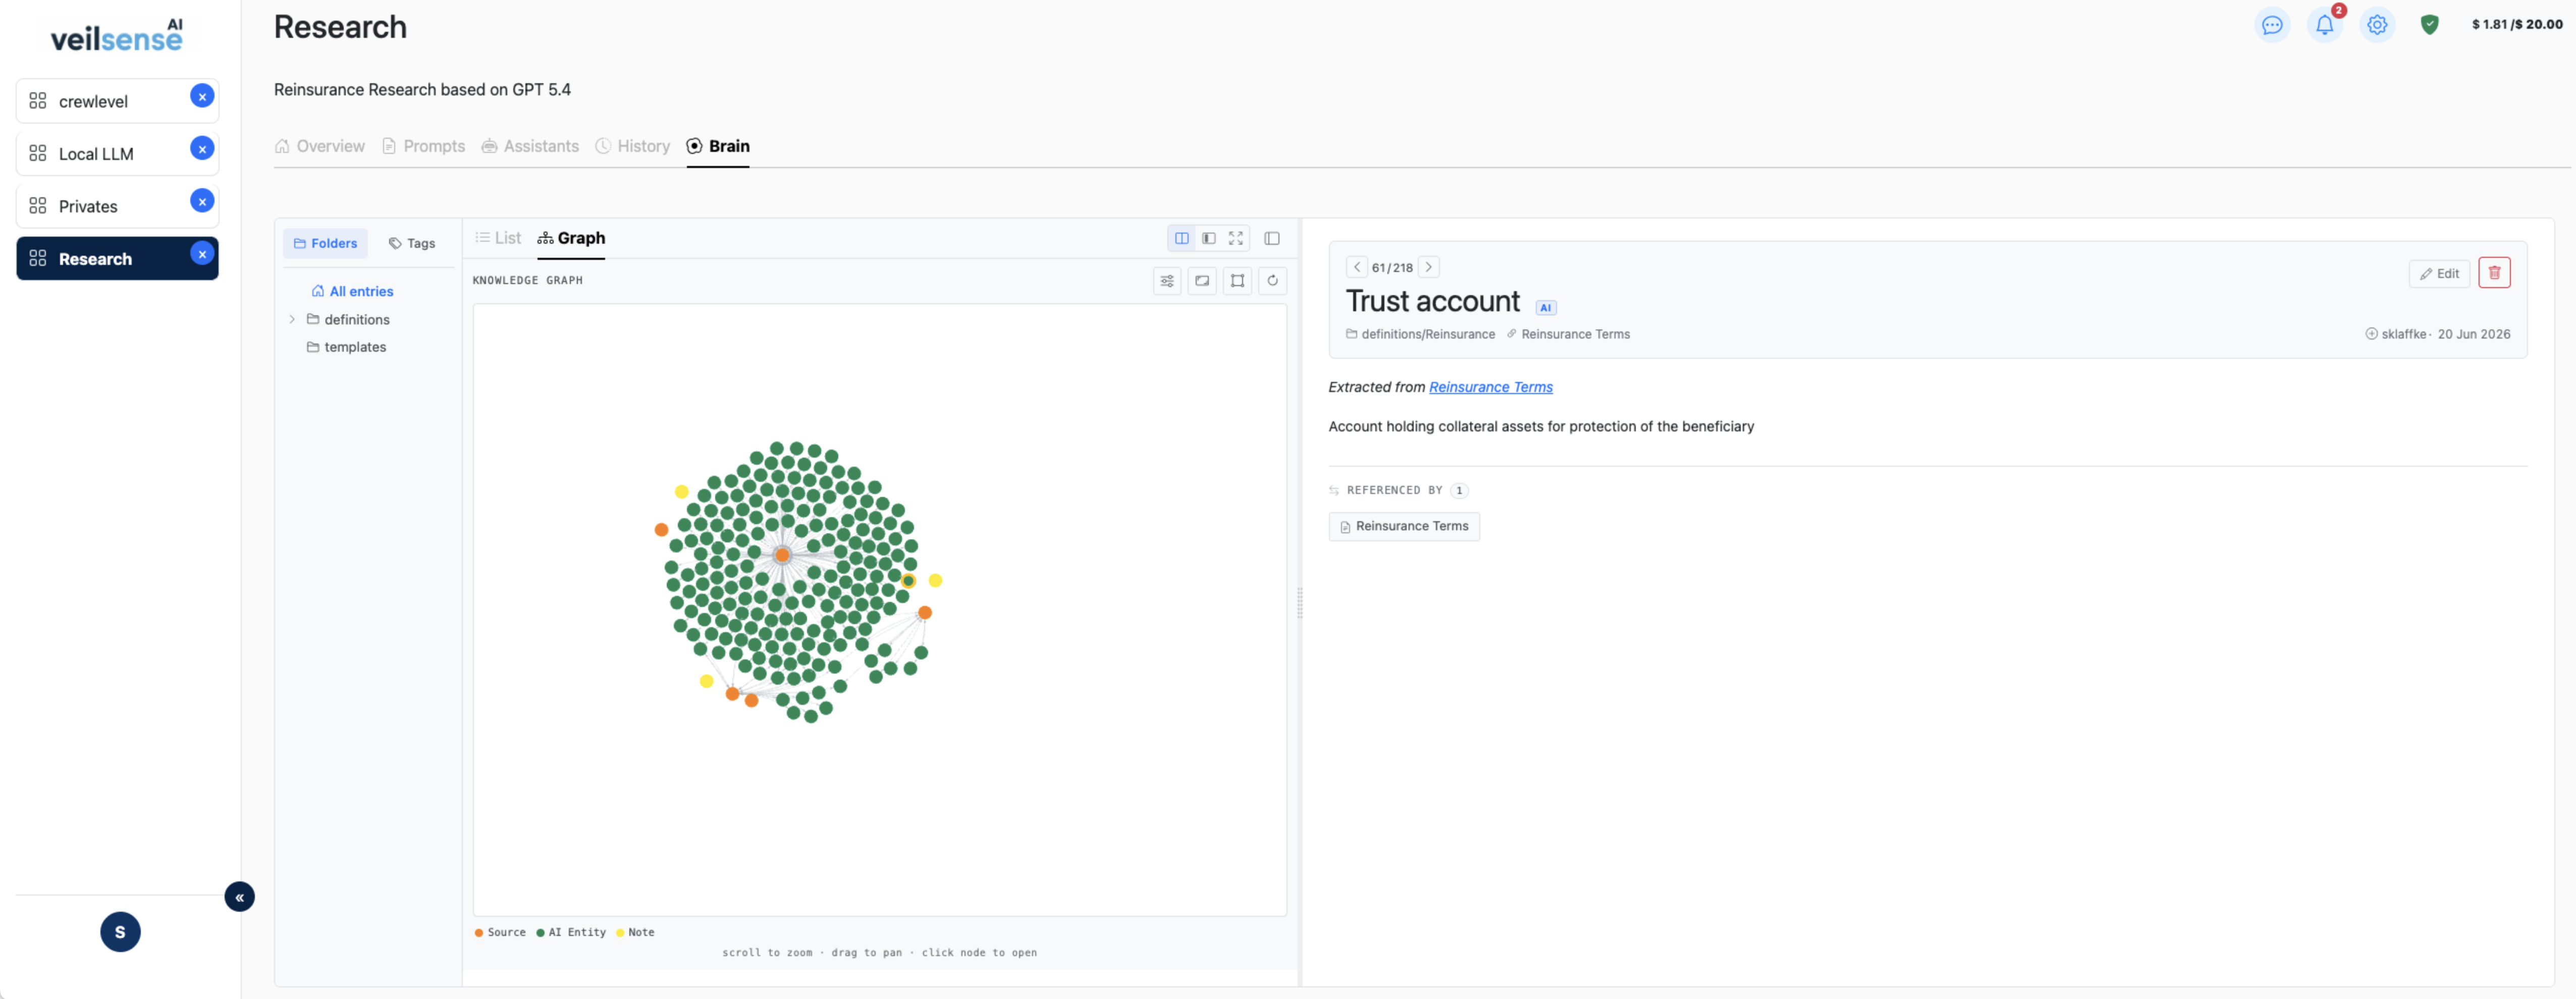
One place for everything your team knows
Collect chat responses, uploaded documents, research, meeting notes, and work results into a single searchable Brain. One source of truth — always up to date.
AI that answers from your data, not guesses
Assistants search your indexed Brain before responding. No hallucinations — every answer is grounded in content you control, not a language model's approximation.
Your LLM, your choice — including local models
Connect OpenAI, Claude, Gemini, or a local Ollama instance. Switch models per workspace without rebuilding anything. No vendor lock-in.
Live in minutes, not months
Pre-built assistants for Q&A, CV matching, data modelling, web research, and Confluence sync — ready to run from day one. No custom prompt engineering required to get started.
Open Source — just install with Docker
veilSense is fully open source. No license required — spin it up with a single Docker Compose command. The only costs are your own LLM API tokens and Tavily credits, billed directly by the provider.
Separate knowledge, restrict access
Organize teams, departments, or clients into isolated workspaces. Each workspace sees only what you allow — no cross-contamination, no accidental leaks.
Reuse your best prompts across the team
Build prompt templates once and share them within a workspace. Standardize how your team interacts with AI — consistent output, no duplicated effort.
Keep AI costs visible and under control
Set a monthly LLM budget per workspace with a warning threshold. A live indicator shows spend vs. limit, and admins are notified when the threshold is reached and when the budget is exceeded. Spend is calculated from a maintained model price list, so every chat, assistant, workflow and agent run has a cost you can trace — no billing surprises.
Know which model earns its cost
One system-wide model catalogue with encrypted keys. A usage map shows which models serve which actions in which workspaces, and compares their speed, tokens per second and cost per 1,000 tokens — local Ollama models included. Set a thinking level per model, and the price list keeps itself current: a weekly check reads the providers' price pages and proposes changes that you approve — nothing changes on its own.
An audit trail for everything your agents do
Every model call (prompt, answer, tokens, cost, thinking level and timing), every tool call, approval and policy decision of your agents and workflows is recorded. Open any row to see why an agent decided what it did, and export a tamper-evident, hash-chained bundle for your auditor. Retention is yours to set.
Keep your Brain current — automatically
Scheduled Research Assistant queries fetch and index web results via Tavily, Google, or Perplexity. Confluence and Notion Sync import your wikis. OneDrive, SharePoint, and Google Drive Sync import your files. Source Monitor watches URLs for changes. Paste any link and the crawler indexes the whole page tree — all stored back into Brain without manual effort.
Ask questions of your spreadsheets — exact numbers
Attach an Excel or CSV file and ask in plain language: totals per region, top customers, hours per person and month as a pivot, as a table or chart. The model only sees the columns and a short anonymized sample; the figures are calculated over every row, so they are exact. Download the result as Excel or save it to Brain — or run the same analysis inside a workflow.
A Brain that knows what is still true
An ontology of classes and typed relations gives your knowledge a shared structure, with AI suggestions you accept. Temporal facts track effective dates and propose when a newer statement replaces an older one — so answers stop quoting outdated figures.
Generate real documents, not slide soup
PowerPoint, Word, and Excel Generators fill your actual corporate templates — native tables, repeatable groups, and real numbers your formulas can total. On-brand output, not a generic AI layout.
A virtual team that does the multi-step work
Agents with roles and an org chart take a task, break it down, delegate among themselves, and bring you a finished deliverable — which always stops at a human review gate before it counts as done.
Chain assistants into workflows — with a human checkpoint
Wire assistants and prompts into a visual pipeline with conditions, loops, and aggregation. Add a Human-in-the-Loop step wherever automation shouldn't run unsupervised.